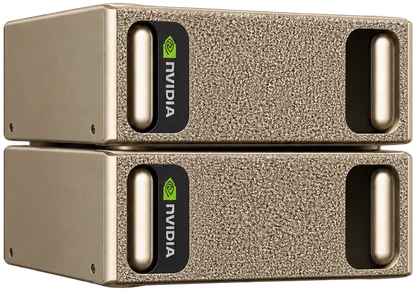
AxForge offering
Subject to confirmed capacity and terms: GB10 is NVIDIA's Grace-Blackwell superchip: an ARM64 Grace CPU and a Blackwell GPU sharing one 128 GB memory pool, which AxForge runs in production and rents as a dedicated DGX Spark in Málaga, Spain. Weights up to roughly 100 GB load on a single chip without sharding, with labelled community benchmarks below.
Check the console for current access, prices and availability.

Why AxForge
| One 128 GB pool | Weights, KV cache and the host share the same memory, so model weights up to roughly 100 GB load on a single GB10 without sharding, with room left for cache and the system. |
|---|---|
| MoE is the sweet spot | Community data (llama.cpp size sweep, Q4_K_M): Qwen3 30B-A3B MoE decodes at 89.3 t/s where a 32B dense model manages 10.7 t/s, because a sparse model only reads its active experts per token. |
| Runs AxForge in production | The same chip serves AxForge serverless inference from Stockholm, and the serving stack runs on ARM64 in production. Prompts on your dedicated machine are never persisted. |
Specifications
| Superchip | NVIDIA GB10 Grace-Blackwell: Grace CPU + Blackwell GPU on one package |
|---|---|
| Memory | 128 GB unified, shared CPU/GPU, no separate VRAM |
| CPU architecture | ARM64 (Grace) |
| Ships in | NVIDIA DGX Spark: dedicated, single-tenant, full SSH access |
| Rental term | Hour, week, month or year |
| Pricing | €1.19/hour on demand · €0.95/hour by the week · €0.91/hour by the month · €0.85/hour by the year |
| Region | Málaga, Spain (eu-es-1) |
| Community decode, 30 to 35B MoE | ~40 to 90 t/s at 4k context. Labelled community data, not ours |
| Trial | Trial access is available for qualifying customers. |
GB10 catalogue reference: specifications and requirements. List prices in EUR.
How it works
| 1 | Confirm capacity and terms in the console before the rental steps below. A public request records demand; it does not reserve or provision a machine. |
|---|---|
| 2 | Sign in to AxForge. |
| 3 | Choose a rental duration: hour, week, month or year. |
| 4 | Check availability, or reserve a start time. |
| 5 | Add your SSH key and connect to your DGX Spark. |
| 6 | Deploy ARM64 builds of your models, containers and serving stack. |
| 7 | End the rental when your workload is complete. |
FAQ
GB10 is NVIDIA's Grace-Blackwell superchip: a Grace ARM64 CPU and a Blackwell GPU sharing 128 GB of unified memory in one pool. It powers the NVIDIA DGX Spark, which is the product you rent.
Community benchmarks (SparkBench, llama.cpp) span roughly 10 tokens/s for 30B-class dense models up to ~90 tokens/s for 30 to 35B MoE at 4k context, with small dense models faster still. These are labelled community numbers, not ours. Architecture, quantization and serving stack dominate.
Capacity and terms must be confirmed before a booking. as a dedicated NVIDIA DGX Spark from AxForge, hosted in Málaga, Spain (eu-es-1) with full SSH access: €1.19/hour on demand, €0.95/hour by the week, €0.91/hour by the month or €0.85/hour by the year.
The 128 GB unified pool means model weights up to roughly 100 GB can load on a single GB10 without sharding across devices, leaving room for KV cache and the system. Production workloads on AxForge nodes are 7B to 35B class models.
Yes. The Grace CPU is ARM64, so software must be built for ARM64. AxForge's own serving stack runs on it in production.
GB10 has plenty of compute but roughly 273 GB/s of memory bandwidth: dense decode is bandwidth-limited, while a sparse MoE only reads its active experts per token. In the community llama.cpp sweep that is 89.3 t/s versus 10.7 t/s.